A practical guide to planning CPU, RAM, GPU, and storage resources for multi-agent AI workloads.
Multi-agent AI infrastructure is becoming increasingly important as businesses move beyond simple AI assistants toward systems that coordinate tasks, analyze data, and automate complex workflows. As these systems grow, infrastructure choices directly influence performance, reliability, and operating costs.
A multi-agent system may include specialized agents for research, data analysis, customer support, coding, or monitoring. Although these agents work together, they do not necessarily need separate physical servers. The right architecture depends on their workloads, resource requirements, and how they interact.
For IT managers, developers, and business decision-makers, the challenge is to balance computing power, workload isolation, flexibility, and cost. Understanding how to allocate resources helps businesses build AI environments that can support production workloads and scale as requirements change.
Understanding the Infrastructure Behind Multi-Agent AI
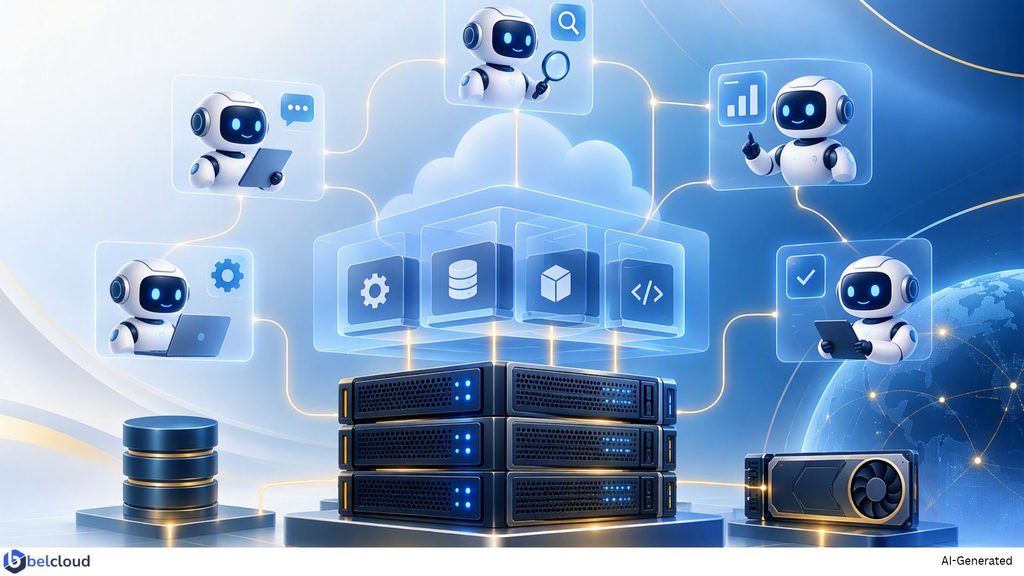
A multi-agent AI system uses multiple agents to perform specialized tasks and coordinate their results. For example, one agent might collect information, another might analyze it, and a third might generate a report from the findings.
Each agent places different demands on infrastructure. Some primarily coordinate API requests to external AI models, while others process data locally, execute code, or run inference using local models.
A system that relies mainly on external APIs may need relatively modest local computing resources. By contrast, deployments running large language models locally or processing substantial datasets may require more CPU capacity, memory, storage throughput, and GPU resources.
When planning infrastructure, businesses should evaluate the workload rather than simply count the number of agents.
Key resources include:
- CPU: Processes application logic, task scheduling, data preparation, and concurrent operations.
- RAM: Supports active processes, loaded models, intermediate data, and application services.
- GPU: Accelerates compatible AI tasks, including local model inference and certain data-processing operations.
- Storage: Holds models, datasets, application files, logs, and temporary data.
- Networking: Connects agents with model endpoints, databases, APIs, and other services.
These requirements provide a practical starting point for determining whether workloads can share a server or need dedicated resources.
One Agent Per Server or Multiple Agents on One Server?
Assigning every AI agent its own physical server can provide dedicated resources, but it can also increase infrastructure costs and management overhead. In many deployments, multiple agents can run on one server if capacity is sufficient and workloads are configured appropriately.
A shared server can work well when agents have moderate resource requirements and their workloads do not consistently compete for the same resources. Process limits, workload scheduling, and monitoring can help prevent one service from consuming capacity needed by others.
However, performance can deteriorate when several agents run CPU-intensive tasks, load large models into memory, or compete for GPU capacity simultaneously. Systems that perform well under normal demand may experience higher latency during peak activity.
Businesses can address these challenges by choosing an appropriate level of workload separation:
- Shared server: Suitable for compatible workloads that can operate within the available resources.
- Virtual machines: Provide separate operating environments and allow CPU, memory, and storage allocations to be configured for individual workloads.
- Containers: Package applications and their dependencies for consistent deployment, with resource controls configured at the host or orchestration level.
- Separate Bare Metal servers: Worth considering when workloads require substantial computing capacity, predictable physical resources, or stronger isolation.
The goal is to match infrastructure to actual workload requirements, rather than deploying more servers than necessary.
Planning CPU, RAM, GPU, and Storage Capacity
Once the deployment model is established, businesses need to estimate resource requirements under realistic operating conditions. Planning should account for concurrent tasks, peak demand, model size, and the overhead introduced by the software environment.
CPU and concurrency
CPU capacity affects how efficiently a server handles simultaneous operations. Agent orchestration, data transformation, retrieval pipelines, and application services may all compete for processor time.
Testing expected concurrency can reveal bottlenecks that average utilization figures may hide. If multiple agents execute demanding tasks at once, sufficient CPU capacity and appropriate process limits can help maintain responsiveness.
RAM and model loading
Memory requirements depend on active processes, model sizes, and the volume of data held in memory. Running several independent model instances can consume substantially more RAM than running lightweight agents that call an external model service.
Monitor memory usage during realistic workloads. Insufficient RAM can cause swapping, increase latency, or lead to process failures when multiple agents operate simultaneously.
GPU capacity
GPU requirements depend on the model architecture, precision, batch size, inference framework, and expected workload. GPU memory is particularly important because models and their working data must fit within available capacity unless supported distribution or offloading techniques are used.
Businesses should verify hardware and software compatibility before deployment. They should also determine how GPU resources will be allocated when multiple agents need acceleration at the same time.
Storage and data access
AI workloads may repeatedly access model files, datasets, indexes, and logs. NVMe storage can benefit applications with demanding data-access requirements, although actual performance also depends on the application, storage configuration, and input/output patterns.
Keep persistent data, temporary files, model assets, and logs organized according to operational needs. Backups and recovery procedures should cover the data and configuration required to restore the environment.
Why Bare Metal Can Be a Strong Foundation for Multi-Agent AI
For demanding AI workloads, Bare Metal servers provide access to dedicated physical resources without the additional virtualization layer typically associated with VPS hosting. This can be valuable for applications requiring substantial CPU capacity, large amounts of memory, local GPU acceleration, or consistent performance under sustained load.
Bare Metal also gives businesses greater control over operating systems, software configurations, and resource allocation, subject to the available hardware and service terms.
A VPS, or Virtual Private Server, is a virtualized hosting environment that can be suitable for lighter services, development workloads, orchestration components, and applications with moderate resource requirements. However, the physical resources underlying a VPS may be shared, depending on the provider’s service design. Businesses running demanding production workloads should assess resource guarantees and performance requirements before choosing VPS over Bare Metal.
Dedicated infrastructure also supports virtualization. Using technologies such as Proxmox VE, businesses can create and manage multiple virtual machines on a single physical server. These environments can separate agent services, databases, development systems, and supporting applications without requiring a different physical server for each component.
For example, a business could run agent orchestration in one virtual machine, model-serving software in another, and monitoring or database services in additional environments. CPU, memory, and storage allocations can be configured to suit each workload.
Virtualization does not eliminate the need for capacity planning. All virtual machines still depend on the underlying server’s physical resources, and GPU passthrough or accelerator sharing requires compatible hardware and software configurations.
This approach gives businesses flexibility to consolidate compatible workloads while retaining the option to add dedicated servers as performance demands or isolation requirements increase.
How Belcloud Supports AI Infrastructure Planning
Every multi-agent deployment has different requirements. The appropriate infrastructure depends on model selection, concurrent workloads, data-handling needs, and performance targets.
Businesses evaluating their options should take the following steps:
- Map agent responsibilities. Identify which agents coordinate tasks, call external APIs, process data locally, or perform model inference.
- Estimate peak resource demand. Assess CPU, RAM, GPU, and storage requirements when multiple agents operate concurrently.
- Select the deployment model. Use shared environments where appropriate and consider dedicated physical resources for demanding workloads.
- Plan virtualization. Use technologies such as Proxmox VE to separate workloads into virtual machines when the server has sufficient capacity.
- Validate GPU requirements. Confirm model compatibility, GPU memory needs, and how accelerator resources will be assigned.
- Monitor performance. Track resource utilization, response times, queue lengths, and failures to identify bottlenecks.
- Prepare for growth and recovery. Document configurations, maintain appropriate backups, and plan how capacity can expand as workloads increase.
Belcloud helps businesses explore hosting infrastructure options that align with their technical requirements, including dedicated infrastructure for workloads that demand greater control and computing capacity.
Build an Infrastructure Strategy That Can Grow with Your AI Workloads
A multi-agent AI system does not automatically require one physical server per agent. Businesses should assess workload demands, identify resource bottlenecks, and select an architecture that balances performance, isolation, and cost.
Virtualized hosting may be sufficient for lighter services, while Bare Metal can provide a stronger foundation for resource-intensive production workloads. With virtualization technologies such as Proxmox VE, businesses can also turn one physical server into multiple managed environments, making better use of available resources.
The right infrastructure strategy gives businesses control over how workloads are deployed today while allowing room for future expansion.
Talk to Belcloud about dedicated infrastructure for your AI workloads.